Refactor vs Rewrite: The Short Answer
Refactoring improves code without changing what it does. A rewrite replaces the codebase, sometimes with a new tech stack or architecture. Refactor when the business logic is worth keeping. Rewrite only when neither the code nor the logic is. And no tests, no refactoring.
| Code quality | Business logic | What to do |
|---|---|---|
| Good | Good | Nothing. Rare, but ideal. |
| Poor | Good | Refactor the code. |
| Good | Poor | Rework the logic, keep the architecture. |
| Poor | Poor | Rewrite from new requirements. |
Need approval? Pitch it as risk and revenue, not code quality. How to get buy-in
You open a file to add a simple configuration flag, and three hours later you're tracing a state mutation across six undocumented helper classes. The developer who wrote it left three years ago, and there are no tests. You have two choices: refactor the mess, or throw it away and rewrite code from scratch.
Diagnose Why the Code Got This Bad
Early in your career, the goal is just getting the feature to ship. You jam the new requirement into an existing function, push the code, and tell yourself the mess isn't your fault, because the file was already terrible.
Eventually, you run git blame on a file that gives you nightmares, and you realize you wrote it 18 months ago.
You can't rewrite your way out of bad habits. If you start a greenfield rewrite, rewriting software without fixing how you write code, you will just build the exact same tar pit in a newer framework.
You don't need to memorize academic definitions of SOLID principles or Clean Code to fix a system; you need to stop writing controllers that parse HTTP requests, execute raw SQL, and trigger email notifications all in the same 500-line method. You have to isolate your business logic from your infrastructure.

Before you change anything, you need a testing strategy. Write a unit test for the function you hate most and count how many dependencies you have to mock. If the setup takes fifty lines, your boundaries are wrong. You have to lock in the current behavior before you start tearing the architecture apart.
You also need a baseline. Run SonarQube against the repository to map out the cyclic dependencies and find the highest-risk files. Don't use it to chase arbitrary test coverage percentages; use it to identify the exact classes that are paralyzing your pipeline so you know where to start.
A new programming language won't fix the boundaries you never drew. Write the tests first, whether you are refactoring in place or starting from scratch.
Decide Whether to Refactor or Rewrite
Rewrite requests almost never come from management. They come from developers who are tired of working in old, slow, complicated code. That's a powerful motivator and a bad advisor: nothing clouds judgment more than pain.
You read a book on software architecture over the weekend, and on Monday you open a core billing module with the intention of cleaning it up. You start renaming variables. Then you extract a 500-line method into five smaller ones. Because the state is tightly coupled, you have to update the function signatures in three other files.
You do this on the main branch. You don't write tests first because you assume you know the workflows. On Tuesday, production goes down because you missed a null check hidden in the original spaghetti code. You freeze deployments for three days while the team reverts the commits.
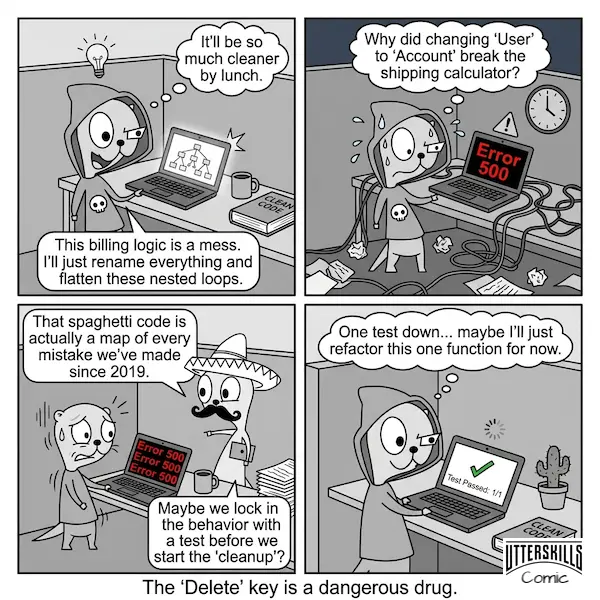
Clean code is not a style preference. When you change the structure of a system without validating its behavior, you break the system.
To avoid bringing down production, you need a framework for the refactor vs rewrite decision. Ask two questions. Is the source code clean enough to change safely? Is the business logic modeled well? The answers put the system in one of four quadrants, summarized in the table at the top. The video walks through each one:
If the application calculates shipping rates correctly but the codebase relies on six levels of nested callbacks and global variables, the business logic is sound. You refactor. You write characterization tests around the inputs and outputs of the shipping calculator to lock in the behavior, then you swap out the internals.
Now take a legacy inventory system where the code is perfectly tested and modular. The problem is the business logic: it was built for single-warehouse fulfillment, and the company just opened three new distribution centers. The architecture is fine, so you keep it and rework the business logic on top of it.
If both are poor, there's nothing left to protect. That's when a rewrite makes sense, and you start from new requirements instead of porting the old code.
One rule of thumb for drawing the line: measure your relative technical debt. If a project took 100 days and would need another 40 to be finished properly, it carries 40% relative technical debt. Past roughly 40%, small refactorings alongside feature work won't keep up. That doesn't make a big-bang rewrite the answer. If the business logic is sound, plan a dedicated project to replace the system piece by piece, with tests carrying the logic over. A rewrite from scratch is still only for when the logic is poor too. Have figures like this ready before anyone asks.
If you decide to rewrite, look at your test coverage. If you cannot write a test suite that captures the current system's behavior, you cannot safely rewrite it. You will spend months chasing feature parity.
If you decide to refactor, don't isolate the work on a long-lived branch. You will spend six weeks restructuring the data layer, only to discover that the rest of the team merged forty conflicting pull requests into main while you were isolated. You will spend more time resolving merge conflicts than you did writing the new logic. Ship the new structure alongside the old one, hide it behind a feature flag, and migrate the traffic incrementally. This is the strangler fig pattern: the new code grows around the old until nothing routes to the old code anymore.
Why Refactorings and Rewrites Fail
The odds of a refactoring or rewrite succeeding are low, mostly because teams don't plan them realistically. Afterwards, management says the developers were incompetent, and the developers say management never gave them a vision. Here are the five reasons on the tech side.
Underestimating complexity and familiarity. Engineers assume the existing codebase is more complicated than necessary and that knowing its flaws makes the new version straightforward. But legacy code is a repository of discovered edge cases. That cryptic regex parsing user inputs exists because a specific enterprise client sends malformed data every Friday. If you throw away the code without understanding it, you throw away the knowledge, and you will have to relearn every edge case in production.
Silver bullet syndrome. The most common trap is the framework rewrite. Your team blames the old routing library for the application's instability, so you spin up a new repository in a modern framework. Six months later, you discover the actual problem was a race condition in the database layer. You just ported the race condition to a new technology stack. A new stack also brings its own questions: can the team handle it, how hard is it to hire for, and what happens when the one advocate who pushed for it leaves the company?
Assuming perfect execution. “This time we'll do it better than the people before us.” Assume they tried hard too. Remember the git blame from earlier: you helped build the mess yourself, and you will make new mistakes in the next version.
Underestimating the value of existing code. Messy code still represents years of investment in understanding and solving the domain's problems, and those solutions have been battle-tested in production. Joel Spolsky made the classic case for this in Things You Should Never Do.
Not willing to go the distance. Teams expect a rewrite to go fast because they already know what the software needs to do. Reaching feature parity takes far longer than planned, and the early enthusiasm turns into hard work. Document every feature of the old application before you start, or a customer will ask why the one feature they liked most is gone.
Even when you avoid all five, expect teething problems. Users have no patience for login errors, broken emails, and strange crashes, no matter how good the new features are. Think of a Formula One car that is faster than the competition but barely finishes a race because it keeps breaking down over small issues. People talk about the breakdowns, not the engine. Small, annoying bugs will get far more attention than your new features.
Take each of the five and ask yourself, on a scale from 1 to 10, how sure you are that your team won't fall for it.
You know the code is bad, and you know how to fix it. But rewriting a core service means halting feature delivery for weeks. If you walk into a planning meeting and ask your product manager for six weeks to improve code quality, they will say no.
Get Buy-In From Management
You inherit a legacy web app. The backend is an unsupported version of Ruby on Rails, the frontend is Ember.js held together by monkey patches, and your GitHub dashboard is a wall of critical security alerts. Upgrading the frameworks is impossible because the dependencies are mutually incompatible.
You and your team are sick of it. You pull your engineering manager and the product lead into a room. You tell them the codebase is a mess, no one understands the event wiring, and you want to spend the next six weeks rewriting it in a modern stack because the current one is dead and you are falling behind industry standards.
The product lead stares at you and says, "The developers who wrote that 'mess' built the product that pays your salary. If you don't understand the codebase, maybe we hired the wrong person. And you want to freeze feature development for a month and a half so you can use a trendier framework?"
Your pitch failed because you pitched your pain. Management does not care about your developer experience. They care about risk and revenue.

If you want approval for a massive structural change, you have to map the technical rot directly to business metrics. If your pitch keeps landing in the backlog anyway, here's why refactoring ideas die there and how to turn technical debt into a decision.
Don't say the code is hard to read. Say it took the team three weeks to add the PayPal integration because the billing module lacks tests. Explain that if you extract the payment gateway into a separate service, you can add Apple Pay and Stripe in four days each. Now you are pitching faster time-to-market.
Don't say you have technical debt. Say the team spends two days every sprint manually resolving stuck database locks. Explain that if you rebuild the data layer, you reclaim that engineering time for new features. Now you are pitching resource optimization.
Don't say the framework is deprecated. Say the current version of Rails stops receiving security patches next month. If a vulnerability is exploited, the company fails the upcoming SOC2 audit and loses the enterprise contract currently in negotiation. Now you are pitching risk mitigation.
Never pitch an open-ended timeline. "A few weeks" sounds to management like six months of zero output. Bring a phased plan. Show exactly what you will cut and what you will keep running. Propose rewriting the highest-churn service first, putting it behind a reverse proxy, and routing 5% of traffic to it. This proves to management that you can deliver value incrementally without betting the entire company on a single, massive cutover.
A software rewrite is a massive financial investment. If you walk into the room sounding like a developer who just wants to play with a new tool, the answer will always be no. Frame the technical cleanup as a business enabler, prove the financial return with historical sprint data, and you won't have to beg the product lead for permission to fix the wall of security alerts.
FAQ
The video above covers the tech side. The second episode, on making a refactoring or rewrite decision-ready for management, is part of our course The Senior Shortcut, along with stakeholder communication, negotiating for engineering time, and the other non-technical skills that determine whether you advance as an engineer.
Author Quote
“Management buys speed, not frameworks”